Backups alone do not provide service continuity. A primary-server failure, database corruption or infrastructure incident can interrupt both websites and turn recovery into a slow, manual and risky process.
CASE STUDY / DATABASE RESILIENCE
Database Resilience & High Availability Architecture
A high-availability architecture for two production websites combining database replication, controlled failover, automated backup and disaster recovery into an engineered business-continuity path.
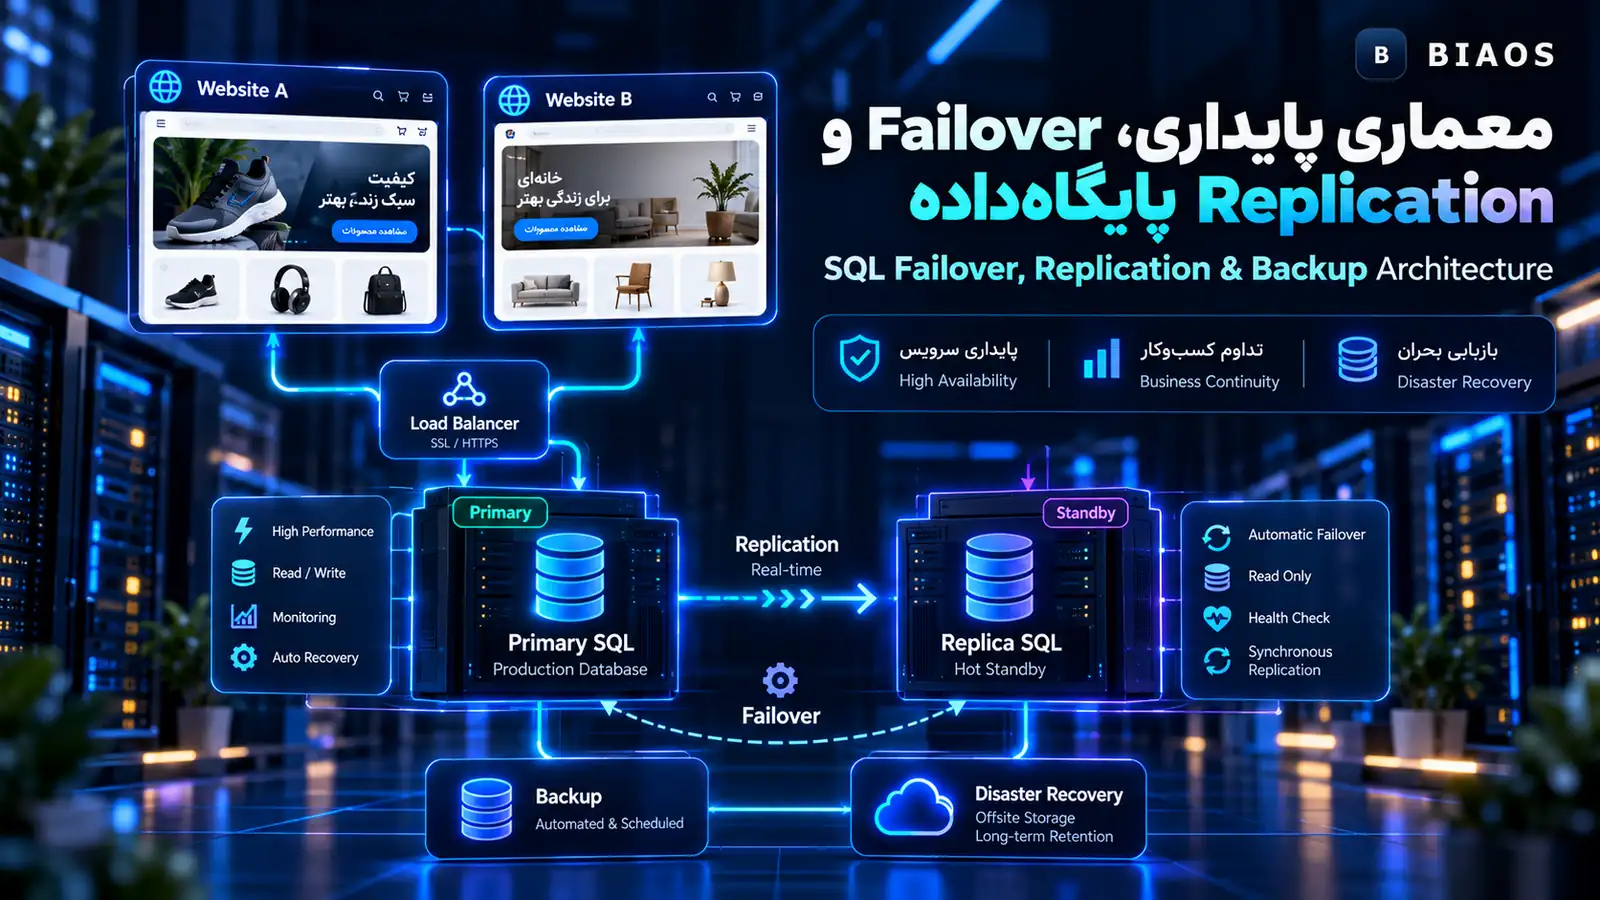
The data layer is designed independently from the websites: the Primary SQL node handles normal read/write workloads, changes are replicated to a standby node, health checks support controlled failover, and scheduled plus off-site backups create a separate disaster-recovery layer.
Two Websites, Resilient Data Layer
Two independent websites can operate on top of a shared resilient data architecture without relying entirely on one point of failure.
SQL Replication
Database changes are replicated from the Primary node to a standby copy prepared for continuity or recovery.
Controlled Failover
Health checks and a controlled switchover path are designed for situations where the Primary node is no longer trustworthy.
Automated Backup
Scheduled backups with defined retention provide a recovery layer independent from database replication.
Disaster Recovery
Off-site copies and a recovery path protect against incidents that extend beyond a single server or database node.
Restore Verification
A backup is only useful when recovery is testable; restore procedures are designed to be documented, repeatable and verifiable.
Reference architecture
Website A / Website B→
Application Layer→
Primary SQL→
Replication→
Replica / Standby→
Failover / Backup / Disaster Recovery
Operational value
The architecture reduces dependency on a single production server or database copy and turns recovery into a planned, testable process designed to reduce downtime and improve operational readiness.